Pokémon TCG: 8,400 game records across 7 opponent implementations
I worked with the team (the AI agents I direct) on automated Pokémon TCG experiments at commit aad907a in thisisntjon/poketcg-research, combining a 4-arm matchup experiment (8,000 games), a later 7-opponent panel of 8,400 recorded games (2026-09-03-strike3-rows.csv) with a 256-unit recurrent learner interface (docs/learner-evidence/README.md) and a Git-pinned research reader (FACTORY-IN-ACTION.md).
Method: the matchup experiment modified makthanithin's Apache-2.0 community_1084 Lucario policy and compared 600 baseline games and 600 counter games against each of 7 opponent implementations (METHODS.md). My competition submission used tetsutani's unmodified public Grimmsnarl policy (docs/EVIDENCE-MAP.md).
Pokémon TCG case study, Machine learning & AI learning laboratory, Learning evidence JSON, Final Report (PDF), Evidence Guide (PDF), Evidence Archive (ZIP), about me, evidence index.
What was built
-
4-arm Lucario matchup experiment: tests 4 policy arms: Baseline, Card only (replacing 1 Carmine with Xerosic's Machinations to reduce a large opposing hand to 3 cards at resolution), Rule only (preferring visible Abra or Kadabra targets) and Combined.
-
256-unit recurrent v2 learner interface and 7 selection checks: encodes acting-player visible state, carries a 256-unit recurrent memory across decisions, scores legal options, and steps through multi-pick prompts with a
STOPaction across 7 component selection checks. -
Research reader repair tested on a synthetic 4/4 wins report: preserves introductory text before section headings so a top-of-file retraction on a synthetic 4/4 wins report survives retrieval and search.
Exact results
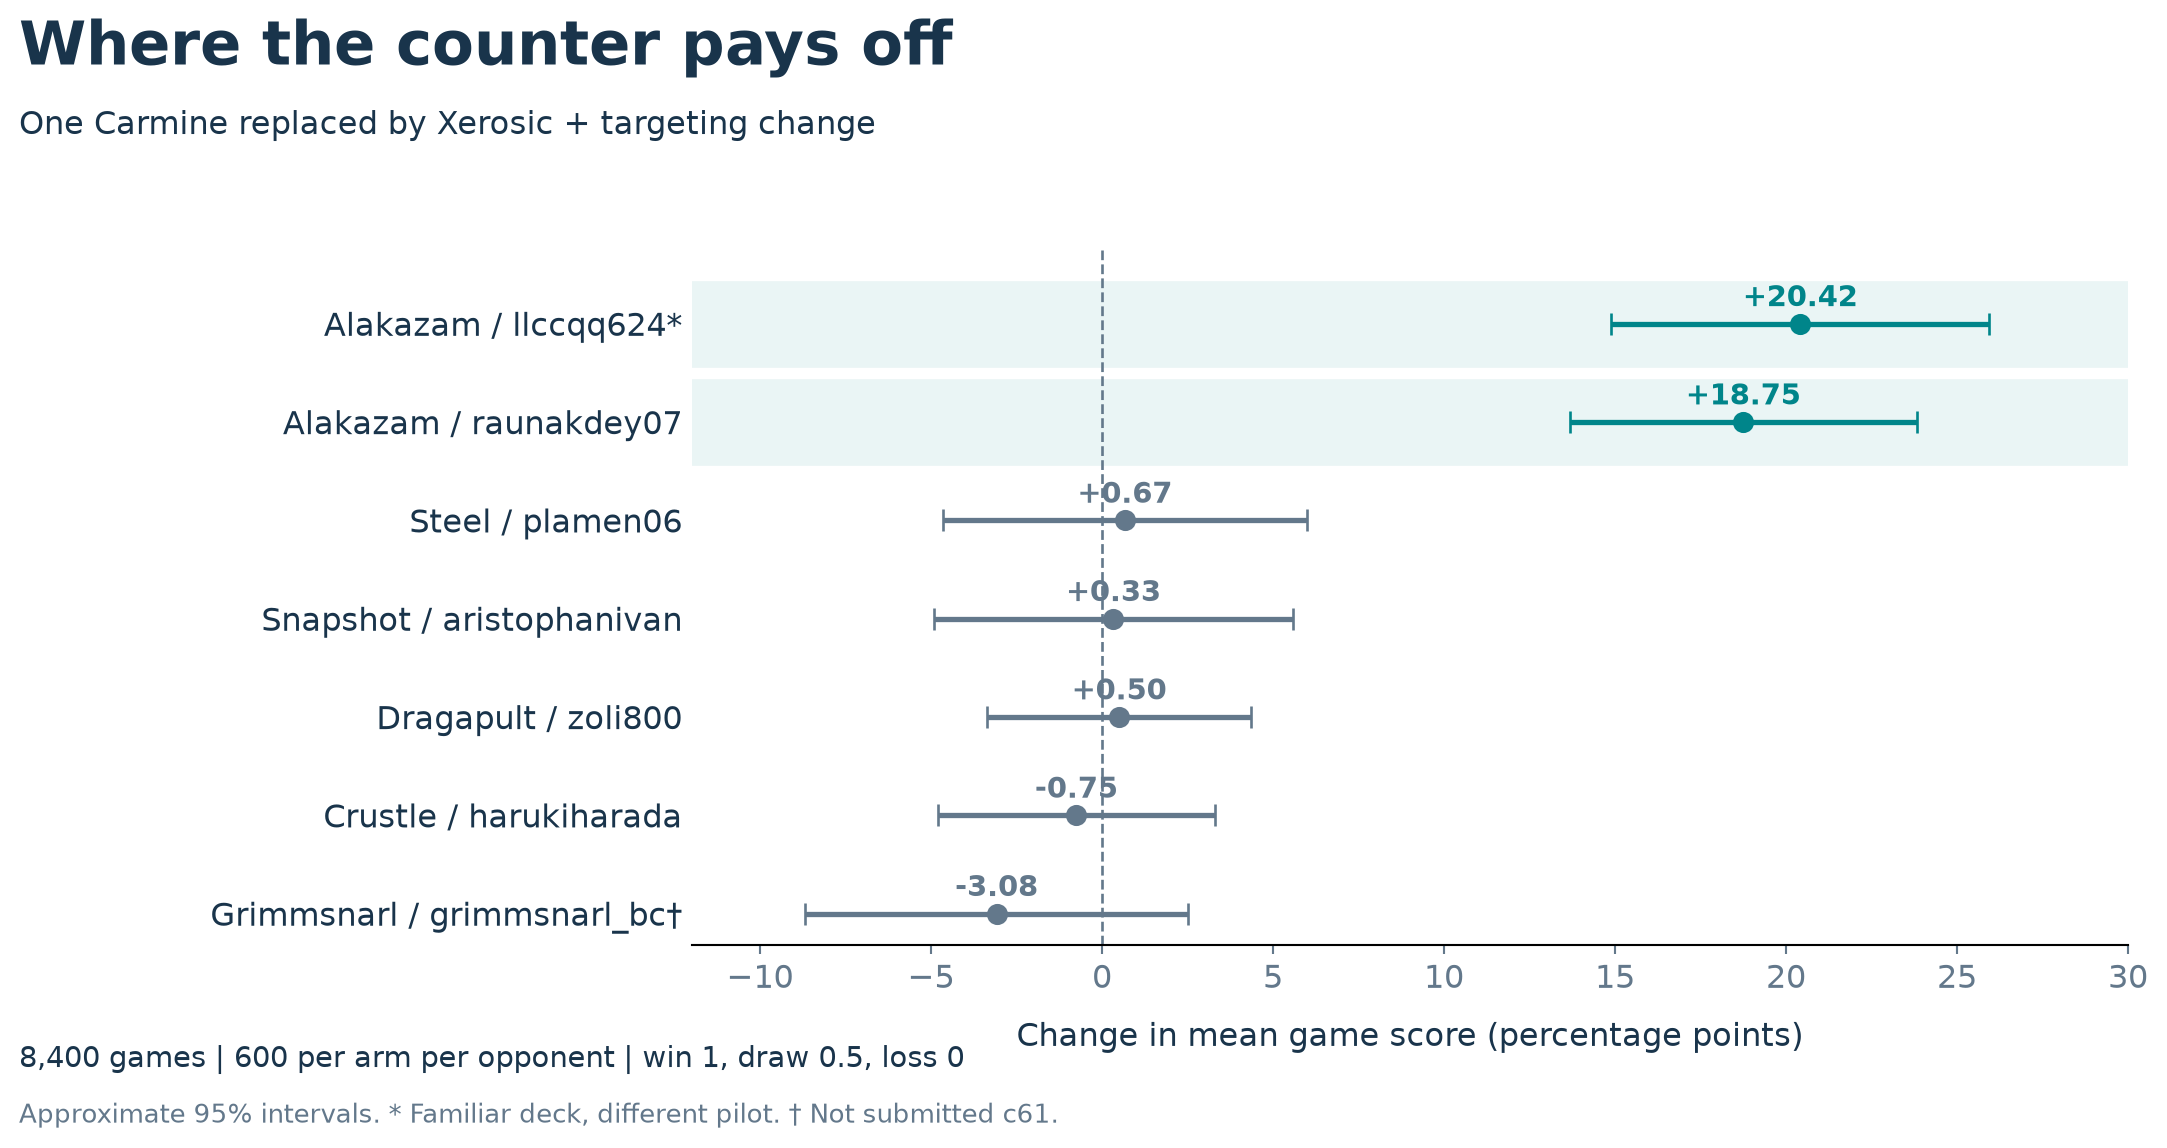
| Opponent Implementation | Games (Baseline / Counter) | Mean Score Change (pp) | Evaluation Note |
|---|---|---|---|
Alakazam / llccqq624 | 600 / 600 | +20.42 pp | Target matchup (deck also used during development with a different pilot) |
Alakazam / raunakdey07 | 600 / 600 | +18.75 pp | Second Alakazam implementation |
Steel / plamen06 | 600 / 600 | +0.67 pp | Non-target opponent |
Dragapult / zoli800 | 600 / 600 | +0.50 pp | Non-target opponent |
Snapshot / aristophanivan | 600 / 600 | +0.33 pp | Non-target opponent |
Crustle / harukiharada | 600 / 600 | -0.75 pp | Non-target opponent |
Grimmsnarl / grimmsnarl_bc | 600 / 600 | -3.08 pp | Non-target opponent (differs from submitted c61 policy) |
-
8,400 game records across 7 opponent implementations: records 600 baseline games and 600 counter games against each of 7 opponent implementations, scoring 1 for a win, 0.5 for a draw and 0 for a loss.
-
+20.42 and +18.75 percentage points against the 2 tested Alakazam implementations: the Combined arm lifted mean game score by +20.42 and +18.75 percentage points against the 2 tested Alakazam implementations.
-
-0.47 percentage points mean change across the other 5 opponents: across the remaining 5 opponent implementations, the mean change was -0.47 percentage points with a 95% interval of [-2.64, +1.71] and individual opponent changes from -3.08 to +0.67 percentage points.
-
23 wins in 1,200 decided games for the earlier August imitation checkpoint: the earlier flat-action imitation checkpoint won 23 of 1,200 decided games against the reference policy, which motivated the v2 legal-option interface.
October 30, 2026: 5,600-game closed-loop action scorer confirmation & ESS = 48.06 diagnosis
In our local PTCG-Learning-Lab workspace, we trained Ridge regression action scorers on 511 eligible first-search development interventions (512 games total) and evaluated them in closed-loop play across three fresh confirmation studies totaling 5,600 games and 1,002,605 verified action records. All three studies proved that the learned weights changed live search choices (266, 812, and 868 changed choices), and all three failed the pre-registered promotion gate requiring a 95% bootstrap confidence interval strictly above 0.0.
| Study & Model Digest | Fresh Games (Actions) | Changed Choices | Score Delta & 95% CI (pp) | Promotion Gate Verdict |
|---|---|---|---|---|
tcg-scorer-v1 (88 features, 52462522...) | 800 (216,710) | 266 | +5.625 pp ([-0.003125, +11.125]) | FAIL (lower bound -0.003125 pp <= 0) |
tcg-scorer-replication-v1 (88 features, 52462522...) | 2,400 (391,026) | 812 | +1.000 pp ([-2.1250, +4.125]) | FAIL (interval includes 0) |
tcg-relational-v1 (90 features, 389221c9...) | 2,400 (394,869) | 868 (99 vs 88-feature) | -1.500 pp ([-4.6667, +1.667]) | FAIL (interval includes 0) |
-
58 score-alias groups across 236 of 511 development rows: in the 88-feature representation, 58 groups of distinct game states produced identical feature vectors despite different visible hands (45 groups also differed in boards), such as
dev-0010vsdev-0145on target card647. -
58 / 511 exact-parent matches (11.35%) and parent_ess = 48.06 under uniform exploration: across the 511 eligible development games, the player faced a mean menu of
10.865legal options, so uniform1/Kexploration matched the exact parent choice only 58 times (14/128, 15/127, 10/128, and 19/128 across the 4 opponent/seat strata), yieldingparent_ess = 48.065and max inverse-propensity weight27.0against a 100-observation direct-comparison screen.
Verify in one minute
Open workflow/research/2026-09-03-strike3-rows.csv and docs/STRATEGY-WRITEUP.md to inspect the 8,400 game rows and the +20.42 and +18.75 percentage point Alakazam gains, or clone thisisntjon/poketcg-research at commit aad907a:
git clone https://github.com/thisisntjon/poketcg-research
cd poketcg-research
git checkout aad907a5b4f9f20de5f591ec49aa2b7ed9c46ea2
Scope of these checks
-
Complete-game win rate for the v2 learner: the 7 selection checks verify the v2 legal-option decoder with fixed scores on CPU; complete-game competitive strength of the v2 learner has not been measured.
-
Non-redistributed assets: trained model weights and 1 development host's raw rows are not redistributed in the public repository.
File details on this page
Format, size and a short SHA-256 identifier, measured when this page was built.
- learning-evidence-record.jsonJSON, 44.6 KB, sha256 b4a0015d2531
- NOTICE.txtText, 1.3 KB, sha256 ea014c7d6343